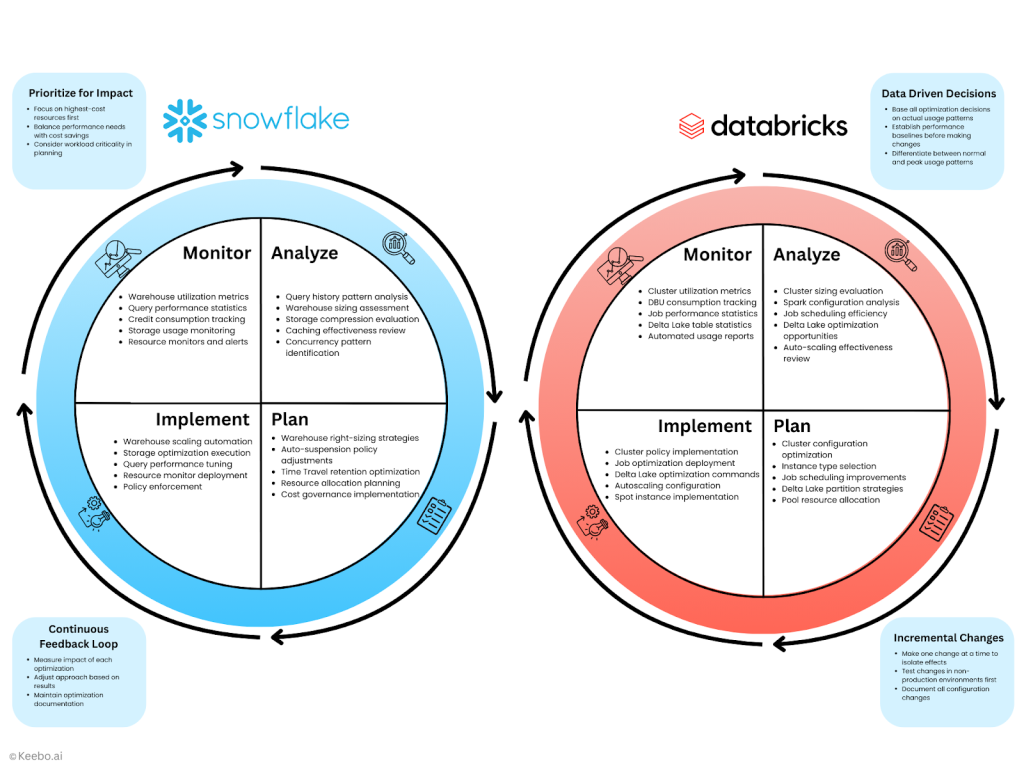
In today’s rapidly evolving data landscape, organizations are continually searching for ways to enhance data processing performance while maintaining cost efficiency. Snowflake, a leading cloud-based data warehousing solution, and Databricks, a collaborative data processing platform, are often used in tandem to achieve robust data analytics capabilities. However, optimizing queries within these platforms is crucial for maximizing performance and reducing latency. Leveraging query optimization techniques can take data processing efficiency to new heights, minimizing resource usage and speeding up data insights.
Understanding Query Optimization in Snowflake and Databricks
Query optimization is a fundamental aspect of database management that focuses on improving the efficiency of executing queries. In Snowflake and Databricks, query optimization can significantly impact the performance of data processing tasks. Here are some key aspects to consider:
- Efficient Use of Resources: Query optimization ensures that the system resources are utilized effectively, reducing unnecessary computations and saving costs.
- Improved Execution Times: Optimized queries run faster, leading to quicker data retrieval and processing, which is crucial for real-time analytics.
- Scalability: Properly optimized queries allow the data infrastructure to scale efficiently with the growing data volume, maintaining performance consistency.
To delve deeper into the specifics of these techniques, explore advanced guides and tips.
Techniques for Optimizing Snowflake Queries
1. Leverage Clustering Keys
Clustering keys in Snowflake help in organizing data within a table, leading to faster query execution. By selecting the right columns for clustering, one can significantly improve data access patterns.
2. Utilize Caching
Snowflake’s caching capabilities can be a game changer in enhancing query performance. By caching frequently accessed data, queries can be executed faster as they avoid repeated data fetching from the disk.
For a detailed understanding, find out more about this approach.
Boosting Databricks Performance
1. Optimize Spark Jobs
Databricks utilizes Apache Spark for processing large datasets. Optimizing Spark jobs is essential to reduce execution times and enhance performance. Techniques include:
- Partitioning Data: Proper partitioning ensures that data is distributed evenly across nodes, preventing bottlenecks.
- Broadcast Joins: Use broadcast joins for small datasets to minimize data shuffling across the cluster.
2. Adaptive Query Execution
Adaptive Query Execution (AQE) is a feature in Databricks that dynamically optimizes queries based on runtime statistics. AQE adjusts execution plans, leading to better resource utilization and faster query completion.
To learn more about tailored solutions in Databricks optimization, discover expert strategies here.
Integrating Snowflake and Databricks for Enhanced Performance
While both Snowflake and Databricks offer individual optimization strategies, integrating these platforms can unlock even greater performance benefits. By combining the strong analytical capabilities of Snowflake with the big data processing power of Databricks, organizations can achieve:
- Seamless Data Processing: Efficiently handle complex data pipelines with integrated query execution.
- Enhanced Data Insights: Generate deeper insights by leveraging the strengths of both platforms.
- Cost Efficiency: Optimize compute resources across both platforms to reduce operational costs.
For more insights into integrating these platforms, learn about our tailored solutions.
In conclusion, query optimization plays a critical role in enhancing the performance of Snowflake and Databricks. By implementing effective optimization techniques, organizations can achieve faster data processing, better resource management, and ultimately drive data-driven decisions more efficiently. Explore advanced guides and tips to take full advantage of these powerful platforms.